


On Tuesday I wrote that the next SaaS migration is your product moving inside your customer’s AI. The comments that caught my attention centered around one theme, although people asked about it from different angles: if the UI goes away, how do you control all the things that the UI enforced? The order things happen in, the defaults, the permissions nobody ever wrote down because the screen took care of them.
We designed UIs for humans, and the good ones were really good at making it feel intuitive. The best software required no training because a new user could see exactly what they needed to do through the workflows in your UI. Now that same effort needs to be applied for agents, through purposeful MCP design, and I think most teams are going to get it wrong the first time, because I did.
Clarabit is the platform Limeade Labs runs on. It’s a fully MCP-driven platform that tracks tasks, work, agent sessions, time spent, and context for you across all your AI tools, so you can keep using Claude, Codex, ChatGPT, Grok, whichever, and they can all share information and hand work to each other. Clarabit does have a UI, and it started off with one, but MCP was in scope from the very beginning, and honestly the UI was mostly for me to debug and troubleshoot things that were difficult to figure out through the MCP. That in itself is a lesson learned. Even so, I made most of the mistakes below, and I think it comes down to this: an MCP isn’t just a wrapper around your API. It needs to be designed as a product surface where the customer is the agent, and I didn’t treat it that way for longer than I should have.
The address field that wasn’t there
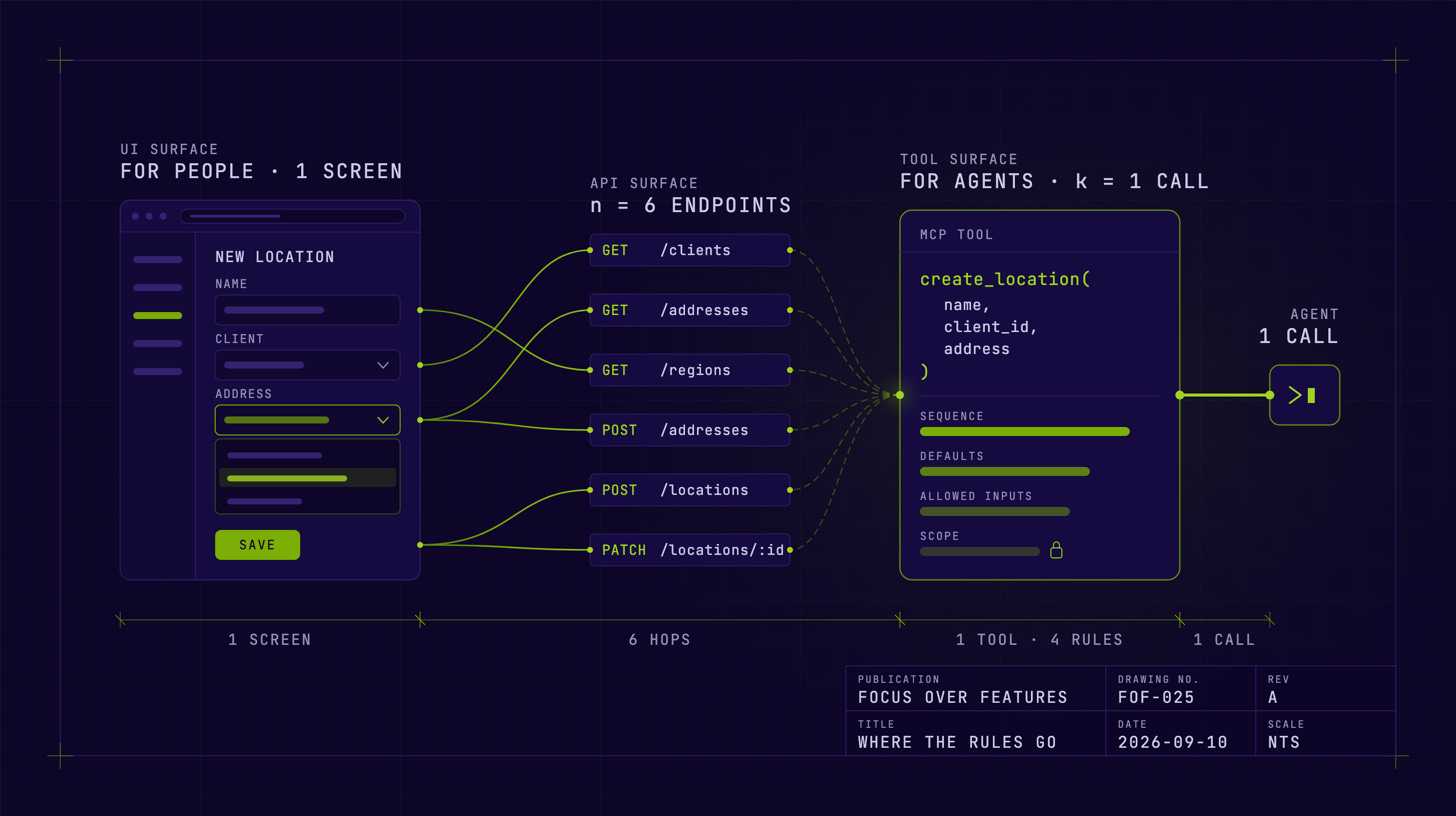
Think back to early CRUD software. Let’s say you wanted to add a new location. You’d name the location, get to the address field, and realize the address field was a dropdown, but it only showed existing addresses, and if you wanted to add an address to the list you couldn’t do that on this view. You had to go to the Addresses view, add the address on that list, save it, then come back to Locations and attach it. I can probably think of a better example of this, but the idea is that nobody designed for the person adding a location. We designed from the systems perspective of a CRUD application, and the screen faithfully exposed the data model.
A lot of SaaS software has an API that’s shaped the same way. Depending on what framework the application uses, endpoints get auto-generated for all the various models in the application, and then there are endpoints specific to particular workflows, and each screen might have numerous endpoints created just so that view can do what it needs to do. Any one of them makes sense. When you look at the API as a whole, it’s a mess.
There’s an exception, and it kind of proves the point. Platforms built from the get-go for other software companies to use often have well-designed APIs, because the API was the product for them. I’ve worked with a lot of vertical B2B SaaS and very rarely does the API get treated like a product. A lot of times it was never intended to be used externally, and then customer requests forced engineering to either carve out a subset as the public API or add better controls around the internal one, plus a lot of documentation and handholding and explaining how to make it work. We struggled with this at Spiffy, where we had a large API set that some third parties were using directly, and we had to figure out a way to document it so they could use it more easily.
Hand that API to an agent and you’ve rebuilt the Locations screen. Say you want to create some new object, and that object in the data model ties back to multiple other data models. If your API only accepts the IDs of those other objects as parameters, the agent has to call a bunch of other endpoints to figure out what the options are, decide, and then put all that back together. It’s a lot of back and forth. Every hop costs context and time, and every hop is a chance to pick the wrong ID. There are plenty of well-designed APIs out there that are focused on a specific task and give you everything you need to do that task in a single endpoint, and an MCP should work very similarly. You should think about an MCP tool the same way you think about a page in your app. What is the agent trying to accomplish, what does it need from the user to do that, and what options and requirements can you hand it up front in the tool description so it doesn’t have to discover them by failing? Otherwise it makes multiple calls, stumbles through it, fails, tries again, realizes it needs to call another endpoint, tries again on the first one. It wastes context, it wastes time. Many platforms have APIs that look very similar to their data model, and that’s fine for your code, but not for a third party. The agent is the ultimate third party.
Not more tools
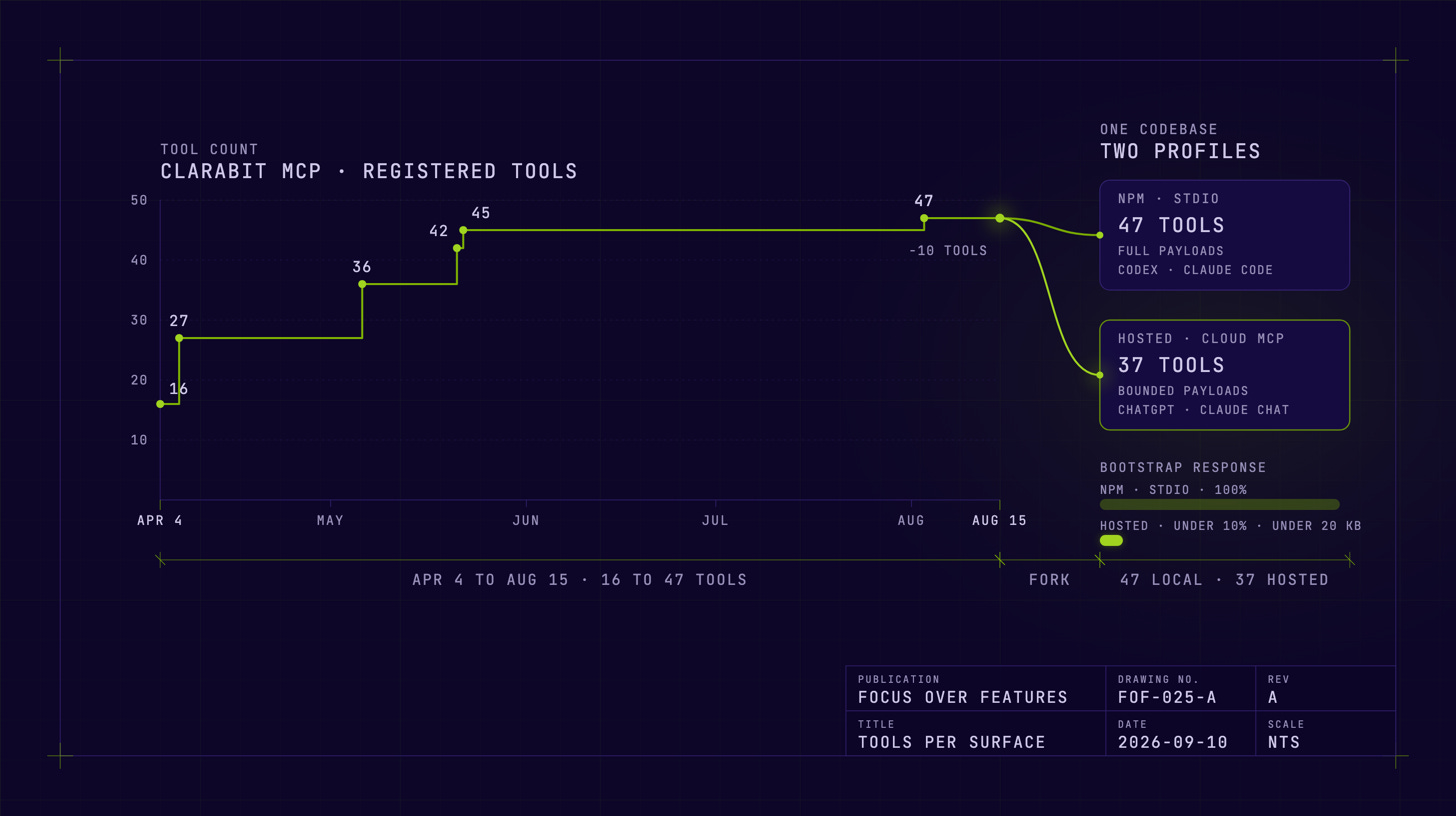
In the earliest versions of Clarabit’s MCP, we built tools for everything. The way to install it was an npm package, context windows were getting fairly large, and I was the only user, so it wasn’t a problem for me. But as the platform grew, the number of tools grew, and it became apparent through day-to-day usage that agents were oftentimes reaching for the wrong tool first. Similar names, dependencies and requirements that weren’t clear from the description. Then we went to make the change to a cloud-hosted MCP so it would work in regular AI chat, as in ChatGPT and Claude chat rather than Claude Code or Codex, and we had new limitations we needed to enforce, because those surfaces have their own limits on what a connection can carry.
We also had to look at what was returned with each tool call. Our initial bootstrap, the first thing an agent calls when it starts a new session, would return all the context for a project. As projects got big and started generating a lot of context, it started chewing up a ton of tokens on decisions from three months ago. So we had to build smarter processing of what context actually matters now, so things that are no longer valid or aren’t needed today don’t get sent with the initial bootstrap. Page revisions had the same problem in reverse: an agent editing a document was sending the whole body back every time, so we implemented delta changes instead.
Most of that work was taking things away. Anthropic and Cloudflare have both argued the count only bites because clients load every definition up front, and that tool search or letting the agent write code against your API will make it moot. Maybe. But the same poor API designs I described above are now showing up in MCP designs, and agents struggle to figure them out. The answer is not more tools; it’s a focus on implementing the guardrails, sequencing, and allowed inputs into the MCP so the agent can be successful. Otherwise you blow out the agent’s context window with wasted information and cause it to thrash with multiple tool calls trying to accomplish a goal, and no amount of clever loading fixes a tool that does the wrong thing once it’s picked.
Two tools that looked the same to the model
Here’s the smallest version of the naming problem. In Clarabit there are a few ways for an agent to upload things: you can attach an inline image to a comment, you can attach an image to the task itself, and you can attach files. Three tools, named similarly, different purposes. Agents would sometimes pick the wrong one. They’d try to upload an attachment that was supposed to live in the body of a comment and it would fail. Or they’d use the comment-attachment tool without creating the comment, which wouldn’t show anything in the UI, so it looked like it succeeded but you’d never see the image on your task, and you had to go tell the agent to create the comment.
The fix wasn’t clever. We enforce those business rules inside the tools now, and we changed the names so the agent knows which one to use in which situation. Every API is different, and building the MCP on top of it requires some real thought around how agents will actually use your platform. Focus on tools that are well-named and self-documenting so the agent chooses the right tool the first time. Every wrong pick is a retry that the person on the other end pays for.
The dashboard has to come to the agent
One commenter asked where the UI’s invisible logic goes, the sequencing and defaults and guardrails nobody documented. Some of it goes into the tools, as above. Some of it runs the other direction, and this is the case that made me see it.
When you’re using many AI tools, sometimes you forget what you were working on across them. A Codex session from this morning, a Claude conversation from the car, a document an agent finished while you were in a meeting. Clarabit has an attention queue for that: the lost sessions and the decisions waiting on you, floated back to you in whatever new session you open. We built a simplistic UI for it, a list on the dashboard. But if you’re operating through the MCP only, with ChatGPT or Claude as your primary work surface, you never look at that dashboard. So the bootstrap call returns the items that need your attention, and the agent is told to let you know about them at the beginning of the conversation. That lets us throw some links in there, and each of those links opens the individual item directly in the embedded browser when you want the full view.
The agent can only do what you can do
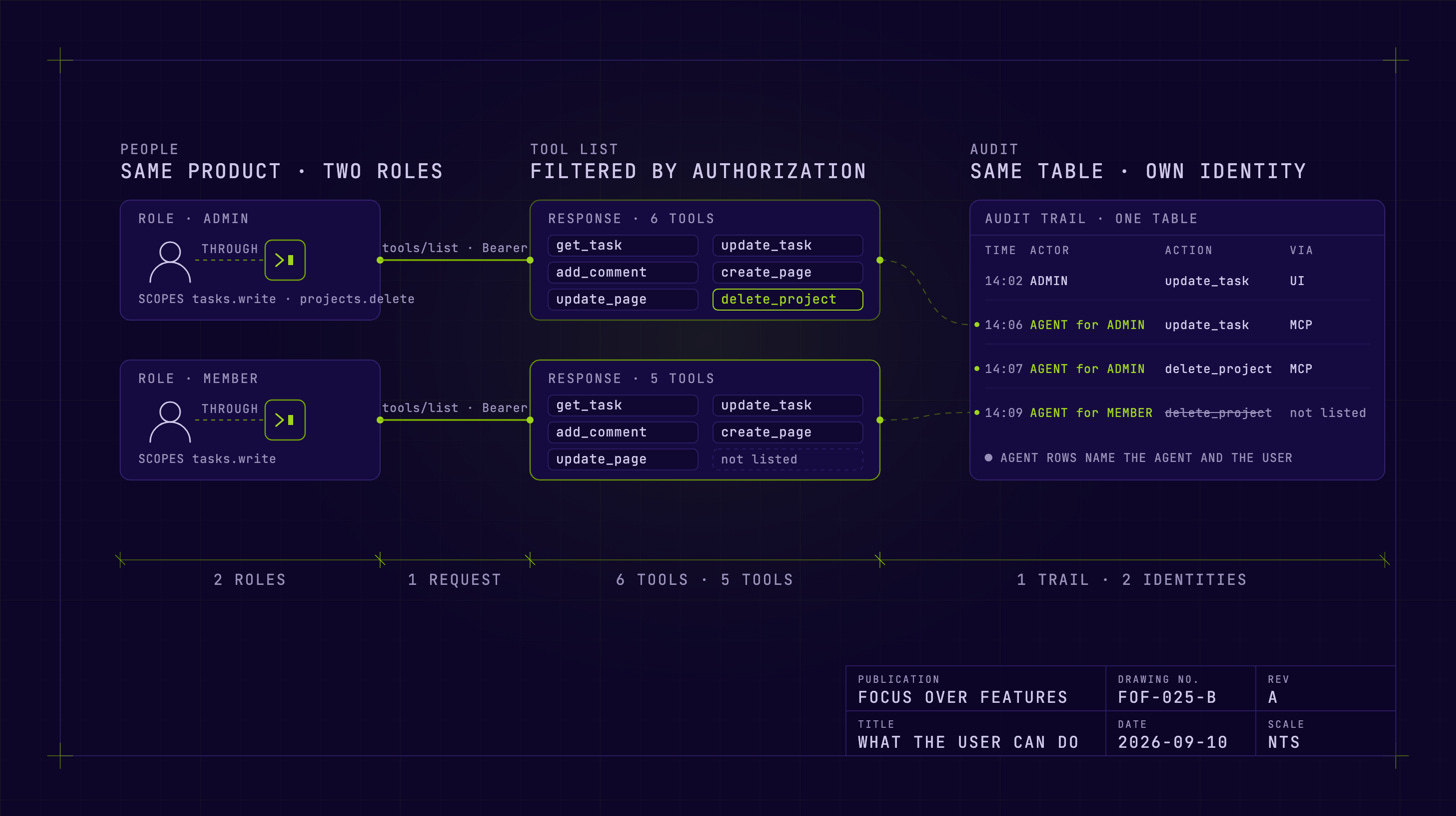
Permissions, I think, is the interesting one, because your users already log into a system and have some set of privileges. Most SaaS software already enforces this. It keeps people from editing things they shouldn’t edit or seeing data they shouldn’t see. An agent should operate the same way. It should have its own authorization context, but it should mirror, and be gated by, whatever the user it’s acting on behalf of can do. If a user is using your MCP with their agent of choice, that agent shouldn’t be able to get around permissions, and it should fail the same way the UI would.
It seems simple. When you start thinking through actual workflows, it gets very difficult to shape the authorization scheme so that the agent knows what it can and can’t do before it tries. The cleanest way I’ve found is to not offer what it can’t use: if a user’s role can’t delete a project, the delete tool shouldn’t be listed for that user’s agent at all. When I was working through this I wasn’t actually sure the protocol allowed it, so I looked. The current spec says the tool list may vary by the authorization presented on the request, and its own example is returning only the tools the caller’s granted scopes permit. A server can also change the list over time and tell the client it changed. So it’s a design choice, and one I’d put on any MCP checklist. In HIPAA or any regulated industry I don’t think there’s another acceptable version.
Logging is table stakes. Your users take actions in the system and you probably already log everything they do. Did they change a setting, did they delete something, can we undo it. An agent should use the same logging, but you don’t want to log it as the user. You want to be able to tell that it was an agent that made the change or accessed the data, and which user that agent was authenticated under, and treat them as separate entities. That way you can audit correctly. If you can’t tell the person’s clicks from the agent’s calls after the fact, you can’t manage what you can’t see.
Every AI app is a different phone
One more thing I'm still mapping, and I'll say up front the research isn't done. Claude, ChatGPT, and the others are different in a lot of ways: which MCPs they support, which sub-features of the protocol, whether they take installed npm packages or cloud MCPs or both, whether you can embed MCP UI, whether you can add a plugin, whether you can embed your own application inside their tool through an internal browser. Whether a voice mode can call tools at all; ChatGPT's can't today. It reminds me of the early app store years, when supporting iPhone and Android meant building twice, and I don't know if there's a better way to describe it yet. I'll write it up properly once I've finished the comparison, because the answer changes month to month.
What would make me wrong
You could argue models will get good enough to work a messy API on their own, and they will. This isn’t new. Users have navigated badly designed software for a long time, and agents are capable of doing the same thing, including pulling up a browser and clicking through your web app directly. Just because an agent can do that doesn’t mean it’s the right way to do it. Ultimately a competitor of yours is going to ship a more efficient MCP that gets the job done faster, with fewer errors, more repeatably, and that’s going to win the user experience long term. The agent picks it. The user never sees the comparison.
Somebody asked me this week what broke first when I built it the first way, the data access model or the workflows. Honestly it was the API design, which like most was aligned with domain data models rather than tasks, and then we had to spend extra time thinking through the enforcement of business logic rules and explaining that logic through the MCP tools. Permissions took the longest. Naming was the cheapest fix and the one I’d skipped. That’s roughly the order I work through now when I look at somebody else’s product at Limeade Labs.
Tuesday’s exercise was to open Claude or ChatGPT and try to use your product from there. Here’s the one that goes with this piece. Pick one screen your customers use every day and write down every rule it enforces that isn’t in your API docs: which field has to be filled in first, what gets defaulted for them, which dropdown only shows what this particular user is allowed to pick, who never sees the delete button at all. That list is what your MCP has to carry, and honestly the length of it is your estimate. I’d like to know how long yours came out. Comment here or find me on LinkedIn.
The invisible rules in a good interface are easy to miss when replacing it with agent tools. I'd map those constraints before deciding what the tool descriptions should say.